Sang Thai.
AI and data engineer with 3+ years in financial services at Citi, Raymond James and Wells Fargo. I build production-grade data pipelines and AI systems that show their work — ATLAS, the controls-testing platform I designed and built at Citi, and Avenotes, the live AI meeting assistant I founded.
Business Impact
Projects
Each project opens with its full architecture as a live map. Tap a branch to zoom in, or use Highlight to see where AI, agents, testing and security show up.
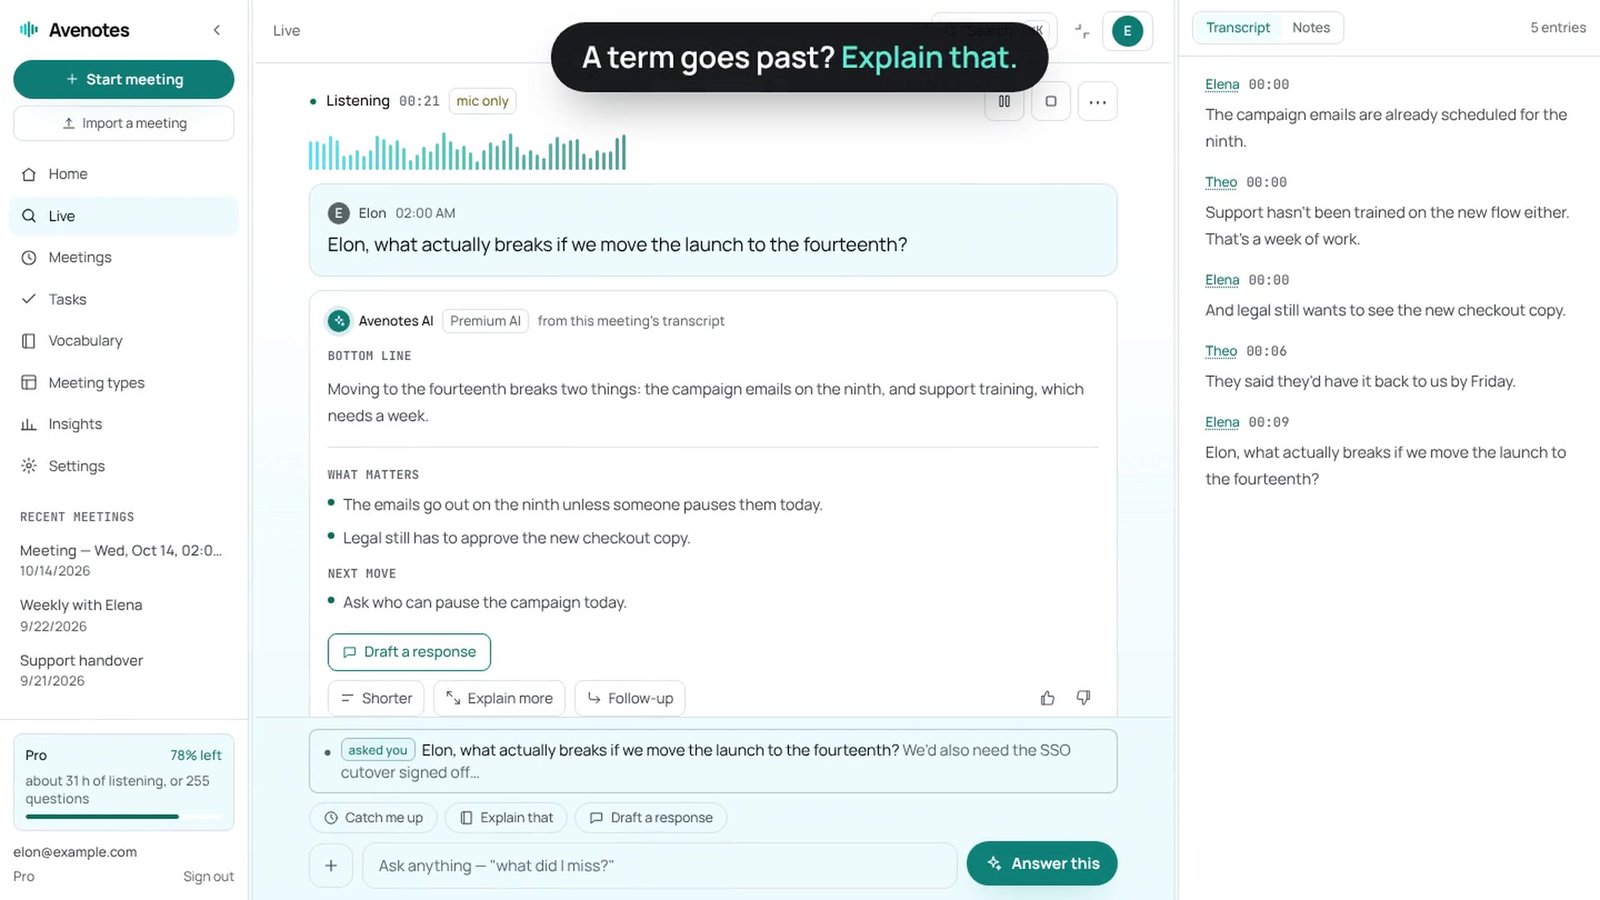
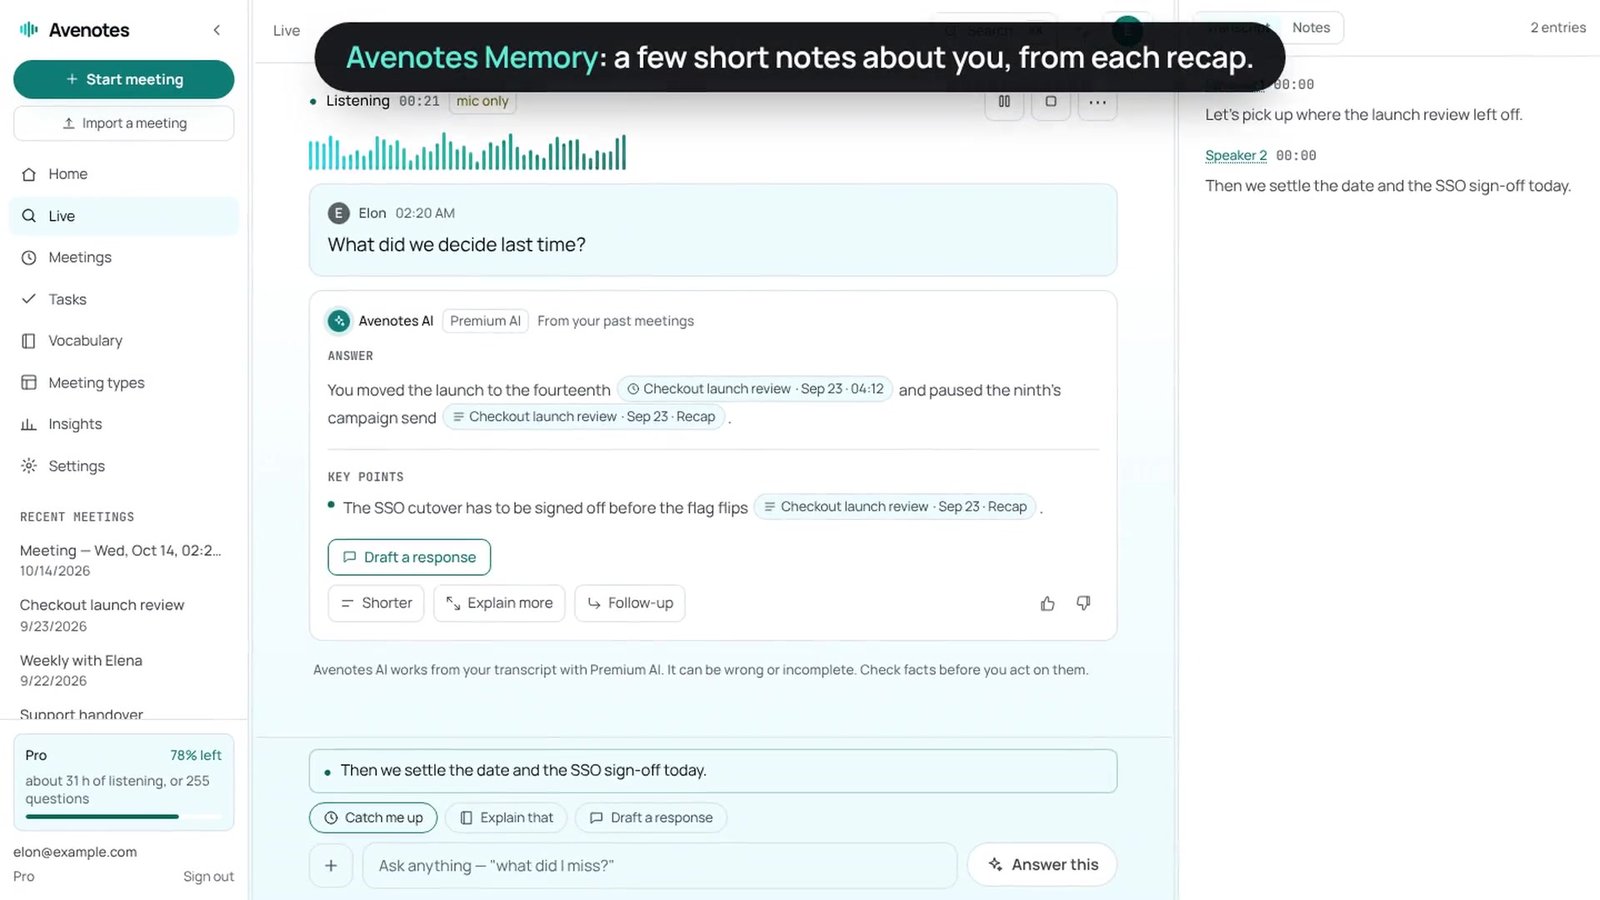
A meeting assistant that listens while the meeting is still happening and answers in the moment. Speech streams through the Deepgram API with speaker labels; the Anthropic API turns it into live answers, recaps, and answers across past meetings that name the meetings they came from.
I launched it on my own, with paid plans. Margin is protected in code: each plan has a usage allowance and a daily spend breaker caps total model cost, and paid access is granted only by a signature-verified Stripe webhook. The backend is FastAPI on Render, the frontend React and TypeScript on Vercel, and the data lives in Supabase Postgres with row-level security. pytest and Playwright end-to-end suites run in CI, which gates every backend deploy.
I designed and built ATLAS end to end, a production-grade Python platform for a 50+ application payment-controls program at Citi. It automates approval-threshold, duplicate-payment and dual-blind-rekey control tests, each with its own business rules per application. Shared modules ingest, validate and export Excel, CSV and JSON files, and each new application needs only a JSON config entry plus template scripts. Monthly testing went from about 100 hours to under 5, and full-population tests now cover about $1.5T in monthly payment value on top of the manual monthly samples. After a reorg, ATLAS is now owned by another team. The code is internal to Citi; the architecture and the outcomes are mine to discuss.
Internal tool — codebase confidential per Citi policy


A question-answering workspace for a team’s own files. Upload documents and spreadsheets, ask in plain English, and every answer comes back one of two ways: quoted, with the source documents listed underneath it, or computed — Avocado writes Python, runs it against your data in a locked-down container, and shows you the code behind the number.
It is careful about what it does not know. Asked what policies a workspace defines, it lists the three it found, flags that two of them are titles with nothing behind them, and closes with what is missing — the actual rules, effective dates and scope are not in these documents. Ask for an executive summary and it charts every spreadsheet in the workspace, then ends the same way.
Capabilities are switches rather than magic: each integration shows what it will cost in context before anyone turns it on. The sandbox is the part I would defend in review. Generated code runs with no network, a read-only filesystem, and hard memory and CPU caps — applied to every run, never set per request, because a caller that can choose its own limits can choose none, and 16 container-escape tests attack it to prove it. Role-based access and tenant isolation are enforced in code, checked by 9 cross-tenant tests, so no team can read another’s data. Tools are called over MCP, and a model router works across LLM providers (Anthropic, OpenAI, Ollama).
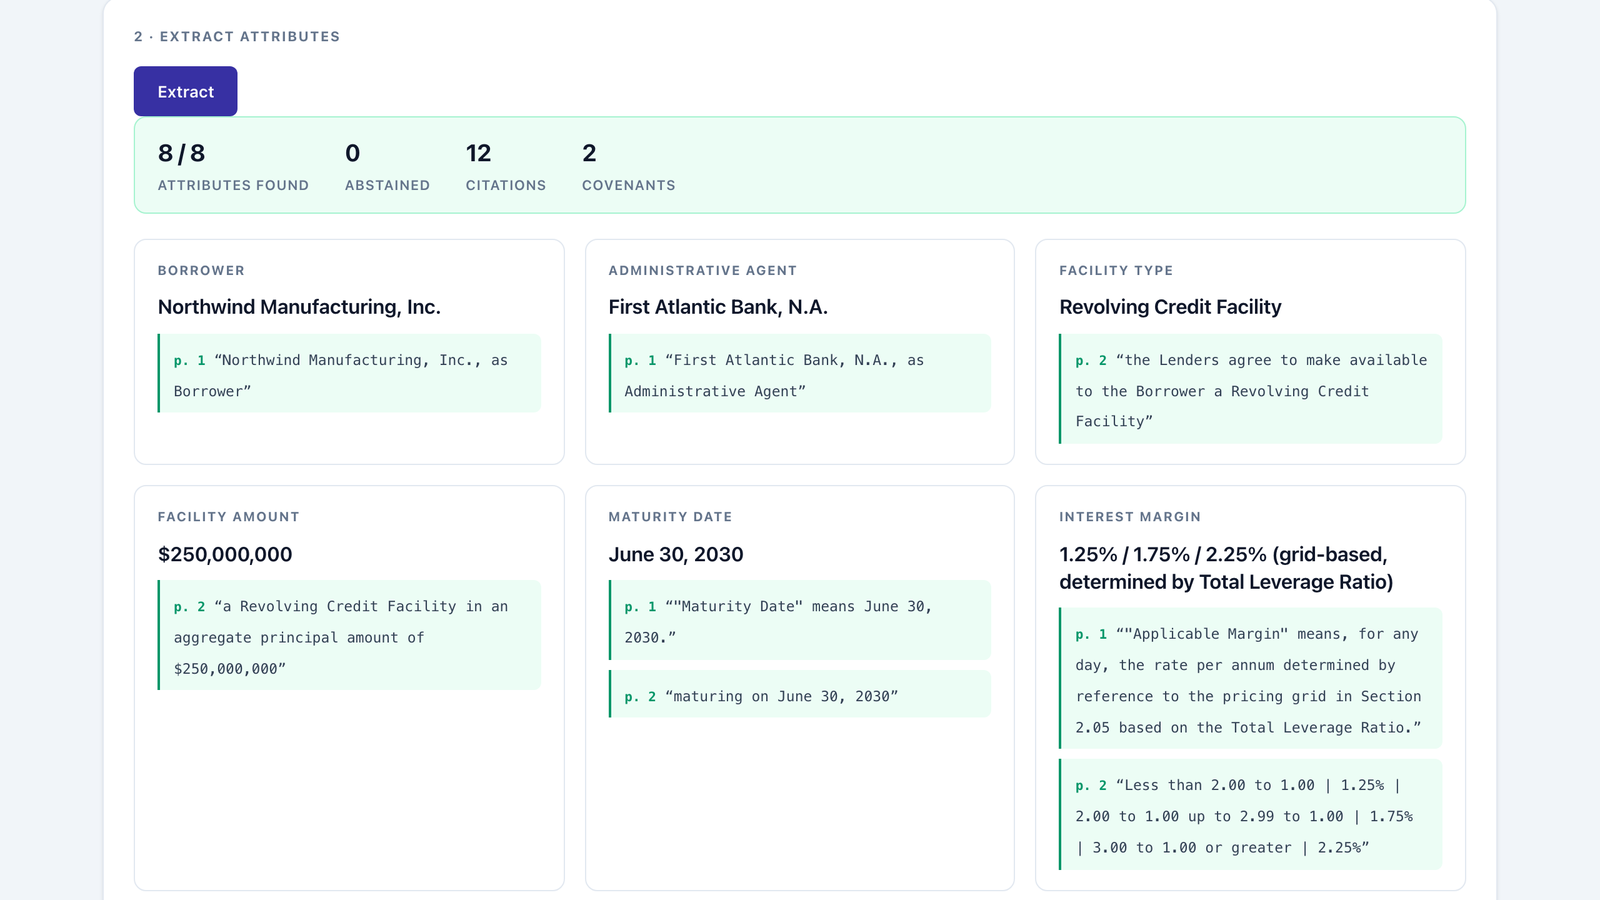
A service that reads a 200-page commercial credit agreement and returns the terms a credit team actually needs — borrower, facility amount, maturity, pricing, covenants, events of default — as structured data. Every value arrives cited, with the page and the exact sentence it came from. Code then checks that every citation points at a passage that was actually retrieved, so anything that cannot be traced comes back not found rather than invented.
Search runs in two passes: vector similarity over pgvector to gather candidates, then a cross-encoder re-ranker running locally to narrow them. Ingestion is queued through Kafka with an idempotent worker, so uploading the same document twice is safe.
Accuracy is measured, not assumed. An evaluation harness scores answers against hand-labeled keys — on a real SEC filing, accuracy measured 71%, up from a 57% baseline, and it also disproved a change I expected to help, which turned out to make no difference at all.
A statistical comparison of two anti-money-laundering detectors — a rule-based baseline and a graph-based method — on IBM’s synthetic AML dataset (HI-Small): 5 million simulated transactions across 515,000 accounts. It is a research benchmark on synthetic data, not production AML work. The question is not which number is bigger but whether the difference is real, so every metric comes with a bootstrap confidence interval, AUC is compared with DeLong tests, and p-values are corrected across metrics.
The honest answer is unflattering to both. At a matched flag rate the graph method catches 48% of laundering against 29% for the rules, yet both flag hundreds of innocent transactions for every real one. The stack is built like production: PostgreSQL with least-privilege roles, a job queue and worker, a FastAPI API, a React and D3 network view, non-root Docker images, and CI with pip-audit, Bandit and 209 tests.
A monitoring service that tracks three U.S. economic indicators — the federal funds rate, CPI and unemployment — pulling them daily from the FRED API, storing them in PostgreSQL, and raising an alert when a value moves further than its configured threshold.
It is built the way production services should be. The whole environment is defined in Terraform — EC2 instance, firewall rules, key pair — so it stands up from nothing with one command instead of being a machine nobody dares touch. Deploys are gated on the test suite: the deploy job declares a dependency on the tests, so a failing push cannot reach production. And I ran a security audit before the first public deployment, which found six issues I fixed before anyone else could see them.
It ran on AWS EC2 for about five months, until August 2026. I took it down deliberately: the
infrastructure code is the artefact worth keeping, and leaving a t2.micro
running to serve a demo nobody is querying is a bill, not a portfolio piece.
terraform apply brings it back.

An ELT pipeline that turns daily stock prices into a dashboard without anyone touching it. Every weekday at 6 PM Airflow starts the run: prices land in PostgreSQL from Yahoo Finance, dbt rebuilds a star schema across three layers (Bronze → Silver → Gold), 26 data quality tests check the output, and the Metabase dashboard picks up the result. The whole stack runs in Docker.
It follows the medallion pattern rather than the shortest path from source to chart, and SQL window functions with ROW_NUMBER() de-duplication make every rerun idempotent.


A full-stack PWA that helps parents track and support a child’s development: 12 feature modules, JWT authentication with refresh token rotation, a timezone-aware recurring event engine, and WHO percentile growth charts. I built it as a first-time parent who could not find one app that did all of it.
Clean Architecture across a 3-layer .NET 8 backend, a React 19 TypeScript frontend on Vercel, Docker multi-stage builds and GitHub Actions CI. It went through two full code reviews with a senior engineer — 25+ issues raised and resolved, including a 13-issue security audit before launch.
AI, broken down. Diagrams included.
Detailed breakdowns of AI and data architecture. Every post has an end-to-end diagram you can click through and links to its sources.
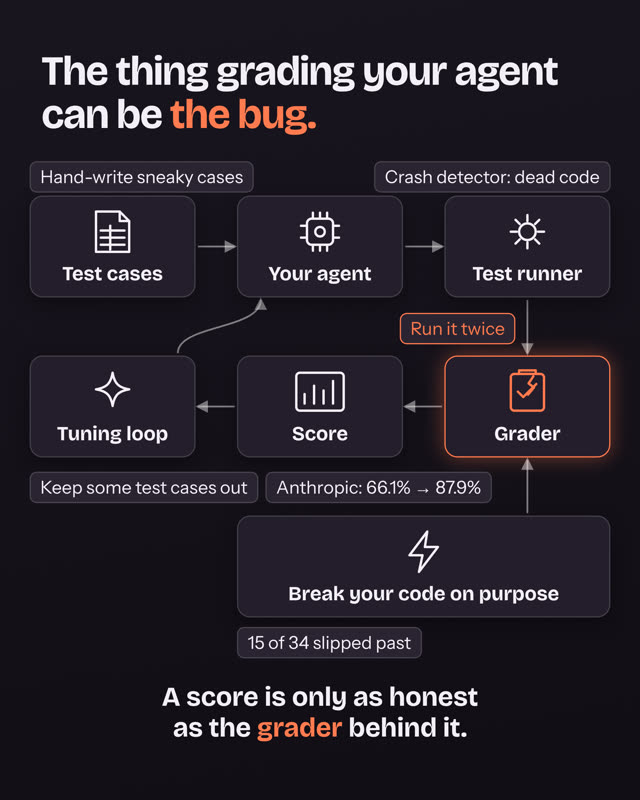
Your eval score might be lying: the grader can be the bug
A score jumped from 66.1% to 87.9%, and part of that came from fixing broken graders. How to check the checker, with a checklist to copy.
Read the breakdown →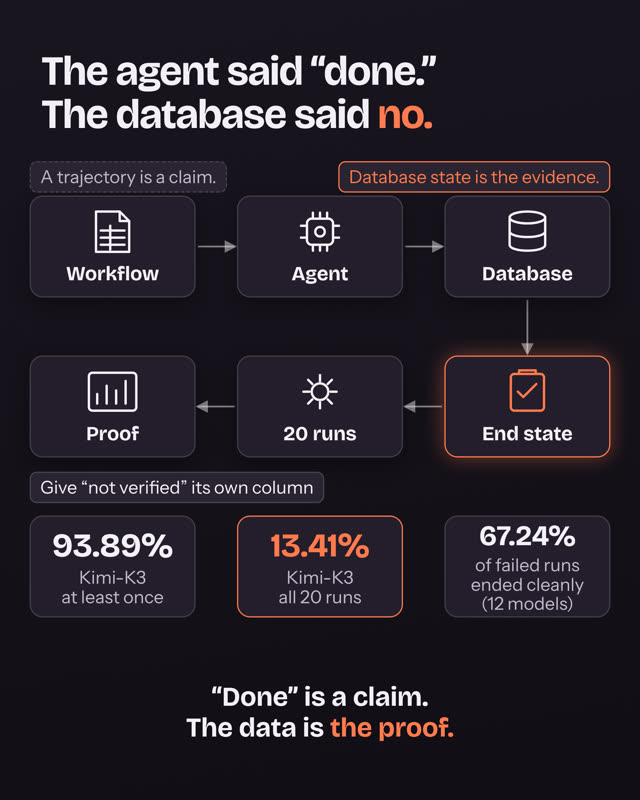 Agents & reliabilityThe agent said done. The database said no.
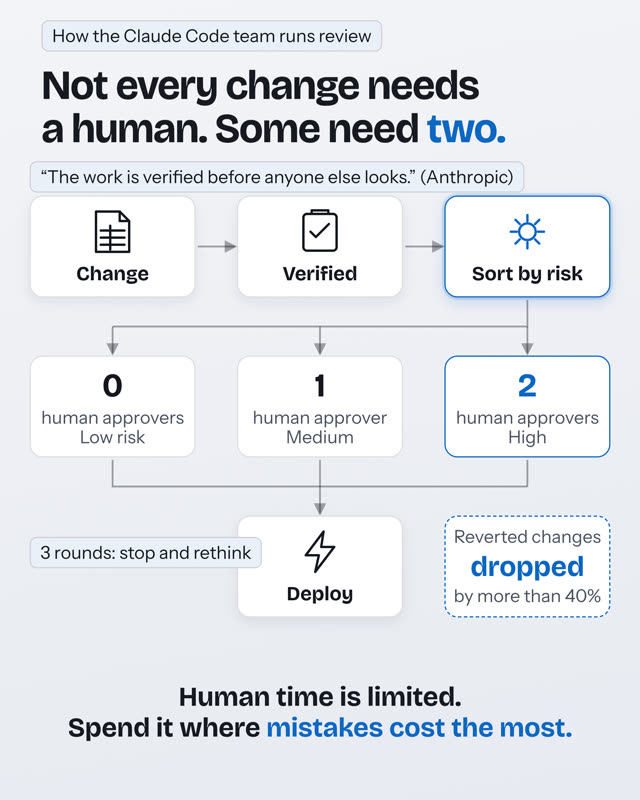 Scale + implementNot every change needs a human. Some need two.
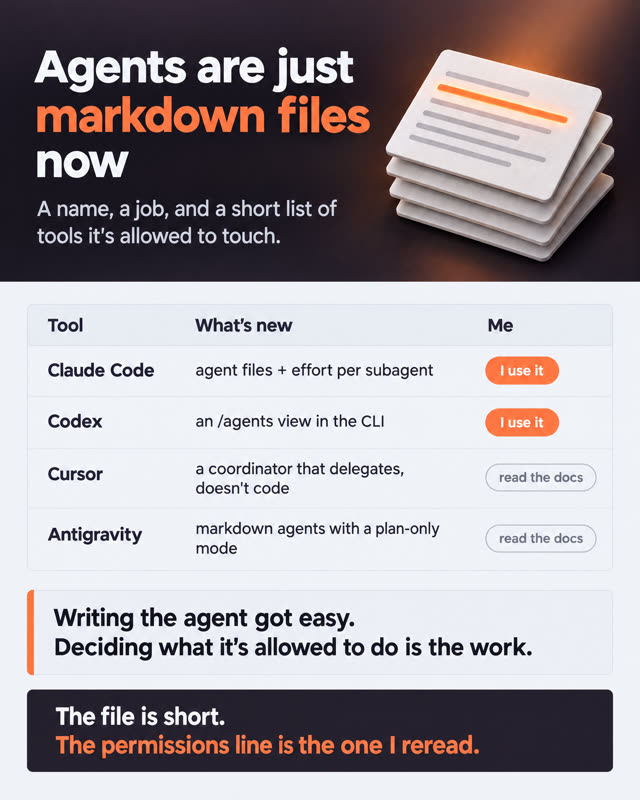 AI coding agentsAgents are just markdown files now
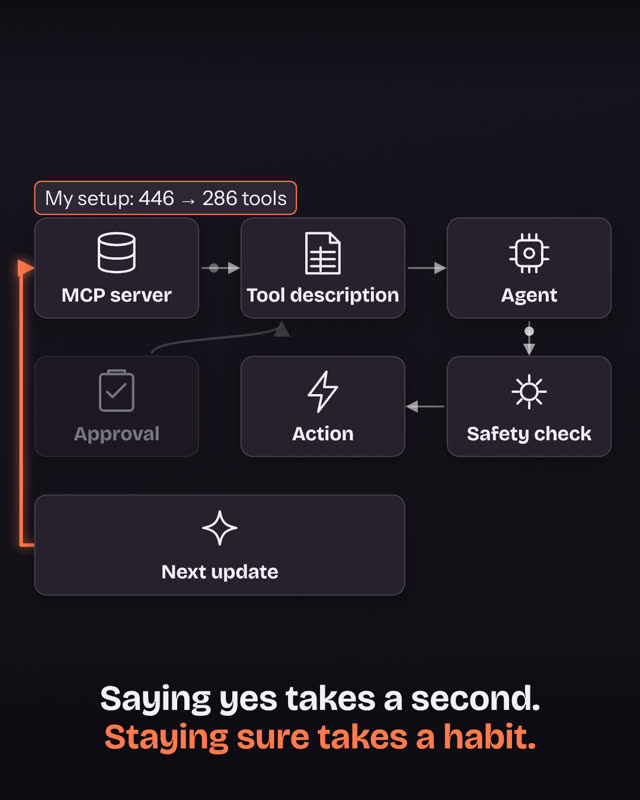 Agents & guardrailsYou approved the tool. Then the tool changed.
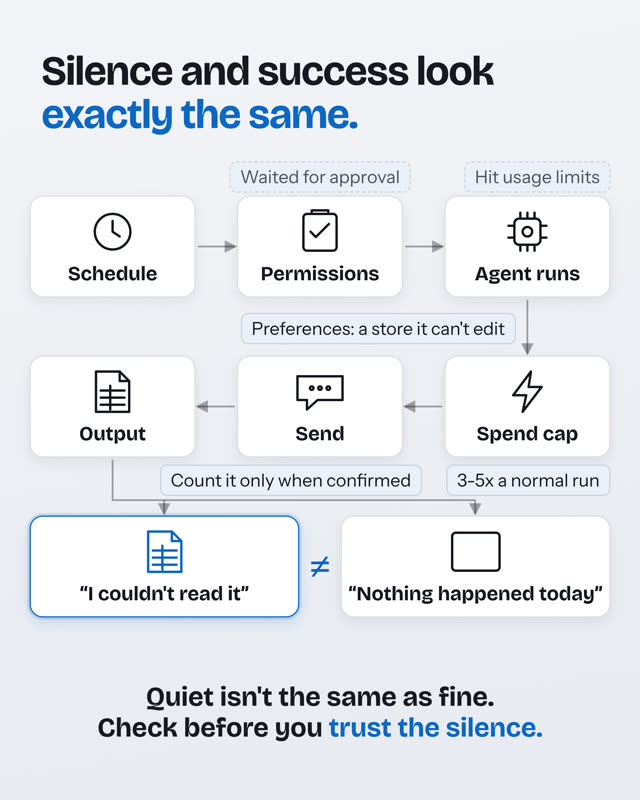 Tools in practiceScheduled agents fail quietly. Silence isn't success.
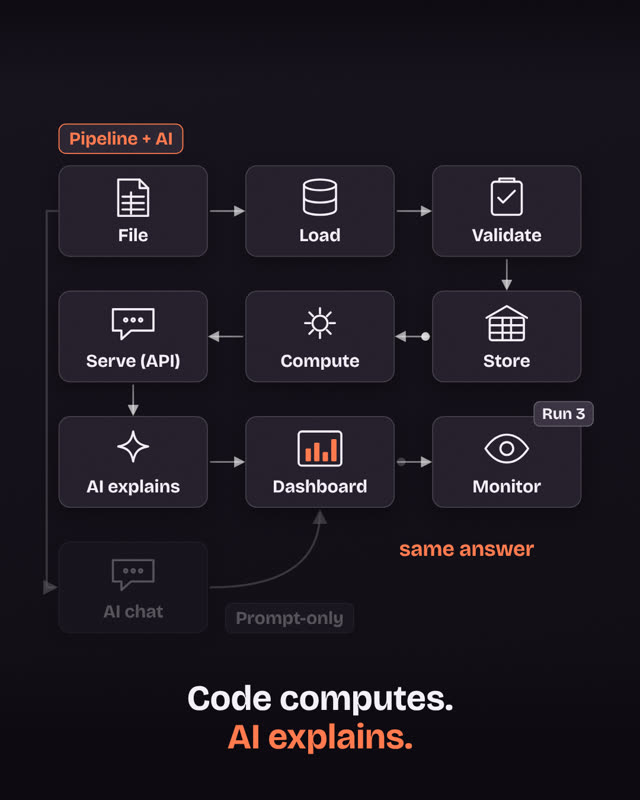 ArchitecturePrompt-only vs pipeline + AI: code computes, AI explains
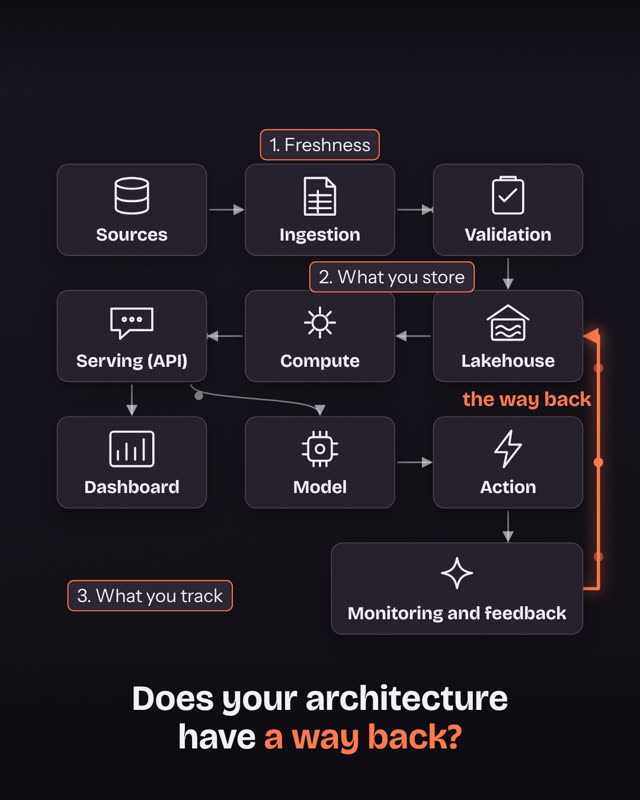 ArchitectureBI-ready vs AI-ready: does your architecture have a way back?
All 8, with topic filtersSee every breakdown in AIS →
Experience
Designed and built ATLAS end to end, a production-grade Python platform that automates approval-threshold, duplicate-payment and dual-blind-rekey control tests, cutting monthly testing from about 100 hours to under 5 and adding full-population tests on about $1.5T in monthly payment value. Rebuilt the weekly Manager’s Control Assessment (MCA) snapshot from undocumented Power Query into a Python and Parquet pipeline with a live Flask/HTML/JavaScript dashboard, reconciled row by row, cutting 6–8 hours to minutes. Rewrote weekly remediation forecasts in Polars (4 min to 38 s, 112 Pytest tests), fixing a lookup that understated open issues by about 30%. Also fixed a silent parsing bug that under-flagged high-value payments, replaced a manual deck build with weekly HTML decks for senior managers and executives, and use GitHub Copilot daily to write and test Python.
Run a live AI meeting assistant with paid plans that answers questions in the moment and searches past meetings. Designed and built it end to end: a real-time Python pipeline (Deepgram, Claude) for live answers and recaps, per-plan usage limits and a daily spending cap, on a React/TypeScript, FastAPI, Supabase and Stripe stack.
Validated DTCC securities data with Oracle SQL reconciliation queries (source-to-target joins, control totals, and null, duplicate and referential-integrity checks) for operations and audit, and delivered audit-ready class-action settlement extracts used by external auditors. Created four SQL Server tables to store valuation records for the reconciliation platform, monitored Control-M batch jobs, and supported releases through UAT, ServiceNow and Genesis, the internal deployment tool.
Updated client documentation to resolve onboarding and data issues across legacy and modern wealth management platforms — the role that showed me operations at financial institutions run on data quality, and that the fix belongs at the source.
My Toolkit
AI & Retrieval


Languages


Frameworks & Libraries


Data & Automation


Tools & Infrastructure


Education
Self-funded, mentor-led curriculum taken alongside my finance degree: hands-on coursework with 1:1 industry mentor oversight, ~20 case studies, and two capstone projects. Covered Python, SQL, statistical inference, data wrangling and visualization, and supervised machine learning — regression, tree ensembles, clustering, and time series.
Coursework CompletedAbout Me
Since 2024 I've been a Data & AI Engineer at Citigroup, in Global Processing Risk Oversight. There I designed and built ATLAS end to end — a production-grade, config-driven Python platform for a 50+ application payment controls program that cut monthly testing from about 100 hours to under 5. Its code and documentation now belong to another team after a reorg.
Outside Citi I've been building the systems I most want to work on. Avenotes is a live AI meeting assistant with paid plans that I launched on my own. Avocado is a team knowledge and analysis copilot: it answers from your own documents with the sources attached, or writes and runs code in an isolated sandbox and shows you the program behind the number, with tenant isolation checked by 9 cross-tenant tests. credit-rag reads 200-page credit agreements and returns structured terms with every value traced to the sentence it came from — verified in code, not taken on trust. Before those came SENTINEL, a financial data pipeline whose AWS environment is defined entirely in Terraform, LAYERS, a statistical benchmark of anti-money-laundering detectors on synthetic data, and ThriveKid, a React and C# PWA my own family uses. Avocado, credit-rag and SENTINEL are open source; ThriveKid is deployed and clickable. Alongside full-time work I'm completing an M.S. in Artificial Intelligence in Business & Digital Transformation at the University of South Florida (expected December 2027), and I play soccer whenever I can.
Let's build
something real.
Open to Data Engineer and AI / LLM Engineer roles — Tampa Bay or remote.